Pfizer logoPfizer Externship via Extern
Joshua Olusanya portrait

Early-career data builder focused on SQL and dashboards

Work samples

Project work includes cleaning six CSVs, designing an analytics schema, and building a Q4 dashboard with SQL and Claude to inform business decisions.

  • Pfizer Advanced: AI-Powered Document Insights & Data Extraction Externship
    Pfizer logo

    Pfizer · ✅ Verified by Extern · ⏱️ In progress

    Pfizer Advanced: AI-Powered Document Insights & Data Extraction Externship

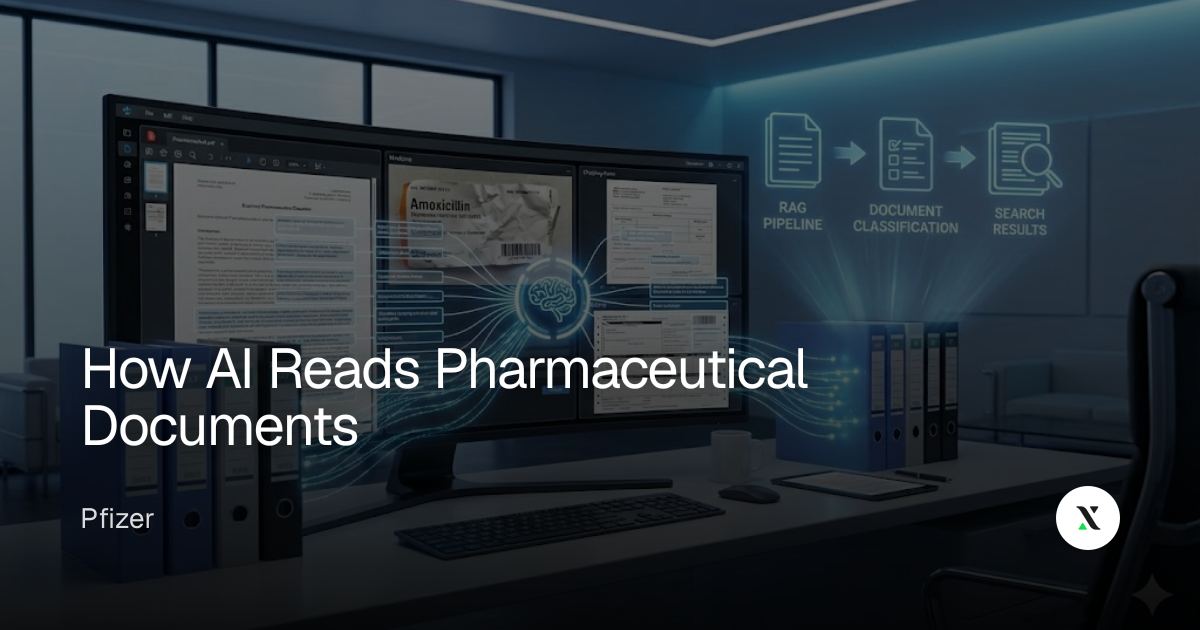
    Prototype AI-powered document intelligence with Pfizer—using OCR, LLMs, and RAG to automate real enterprise PDF workflows and build a standout portfolio project.

    AI & MLPythonDocument IntelligencePresentation Skills
About me

I'm Joshua Olusanya. I'm just starting my career and learning practical data skills through project work. I completed a SQL and database architecture externship with Breaking Games where I turned six CSV files into an analytics database and built a Q4 dashboard using SQL and Claude.

Externships

Pfizer Advanced: AI-Powered Document Insights & Data Extraction Externship

In progress

Skills

SQLDatabase architectureData cleaning (CSV)Dashboard designUsing Claude for data tasks

✅ Verified by Extern · ⏱️ In progress

Pfizer Advanced: AI-Powered Document Insights & Data Extraction Externship

Prototype AI-powered document intelligence with Pfizer—using OCR, LLMs, and RAG to automate real enterprise PDF workflows and build a standout portfolio project.

AI & MLPythonDocument IntelligencePresentation Skills

Overview

The project prototyped an AI document-insights pipeline integrating OCR, language models, and retrieval to process enterprise PDFs. The work surveyed LLM architectures and inference patterns, then mapped how those models could be combined with OCR and retrieval components for document extraction and question-answering.

Pfizer Advanced: AI-Powered Document Insights & Data Extraction Externship

What I've accomplished

I produced a technical write-up explaining how LLMs tokenize text, apply transformer self-attention, undergo pre-training, and are fine-tuned with examples and human feedback, and mapped those mechanisms to document-processing pipelines.

Project breakdown

I described how LLMs break text into tokens, use transformer self-attention to model context, undergo pre-training on large corpora, and are fine-tuned with examples and human feedback to improve accuracy and safety.

View all work