Pfizer logoPfizer Externship via Extern
Pradeep 47 portrait

Product designer and ML prototyper focused on document intelligence

I create prototypes that use OCR, LLMs, and RAG to automate enterprise PDF workflows and show practical results for hiring teams.

Work samples

Projects include an externship prototype with Pfizer that automated PDF workflows using OCR, LLMs, and retrieval-augmented generation, shown as production-style demos and documentation.

  • Pfizer Advanced: AI-Powered Document Insights & Data Extraction Externship
    Pfizer Advanced: AI-Powered Document Insights & Data Extraction Externship
    Pfizer logo

    Pfizer · ✅ Verified by Extern · ⏱️ In progress

    Pfizer Advanced: AI-Powered Document Insights & Data Extraction Externship

    Prototype AI-powered document intelligence with Pfizer—using OCR, LLMs, and RAG to automate real enterprise PDF workflows and build a standout portfolio project.

    AI & MLPythonDocument IntelligencePresentation Skills
  • decifur.ai , Biomedical RAG Research Assistant
    decifur.ai , Biomedical RAG Research Assistant

    Designed and built a hybrid RAG pipeline combining Neo4j knowledge graphs, FAISS dense retrieval, BM25 sparse search, and reciprocal rank fusion to eliminate siloed retrieval over a 300+ paper biomedical corpus, demonstrating proficiency with structured reasoning approaches and NLP-/ontology-powered layering. Achieved a 35% improvement in answer relevance over single-retriever baselines. Integrated UMLS/BioPortal entity normalization and Persistent Conversational Context (PCC) memory into the query pipeline using prompt engineering and in-context learning (ICL) to ground multi-turn scientific Q&A in domain ontologies , reducing entity disambiguation errors by ~40% across evaluation queries. Fine-tuned Qwen3.5-27B on 7,700 biomedical chunks (CPT) + 1,515 Q&A pairs (SFT) via Unsloth/TRL on RunPod H100/A100 , to adapt the base model to chemotaxis research language , achieving 87% answer accuracy on held-out domain Q&A vs. 61% for the off-the-shelf model.

    Neo4jFAISSBM25UMLSBioPortalQwen3.5-27BUnslothTRLRunPodH100A100

About me

I create prototypes that use OCR, LLMs, and RAG to automate enterprise PDF workflows and show practical results for hiring teams.

I hold a masters degree and Im returning to the workforce after a career break. I build data-driven prototypes that apply OCR, large language models, and retrieval-augmented generation to document workflows. I am focused on strengthening my resume with hands-on projects and clear, demonstrable outcomes.

Externships

Pfizer Advanced: AI-Powered Document Insights & Data Extraction Externship

In progress

Experience

Consultant

Extern, Pfizer · June 2026 – Present

Project Manager

DXC Technology · Sept 2023 - Aug 2024

Data Analyst / Data Engineer

DXC Technology · July 2020 - Aug 2023

Education

Yeshiva University, Katz School of Health and Science

Master’s in data Analytics and Visualization · Class of May 2026

Anil Neerukonda Institute of Technology & Sciences

Bachelors in Electronics & Communications Engineering · Class of Sept 2020

Skills

OCR implementation and tuningLarge language models (LLMs)Retrieval-augmented generation (RAG)Document data extractionPrototype design and validation

✅ Verified by Extern · ⏱️ In progress

Pfizer Advanced: AI-Powered Document Insights & Data Extraction Externship

Prototype AI-powered document intelligence with Pfizer—using OCR, LLMs, and RAG to automate real enterprise PDF workflows and build a standout portfolio project.

AI & MLPythonDocument IntelligencePresentation Skills

Overview

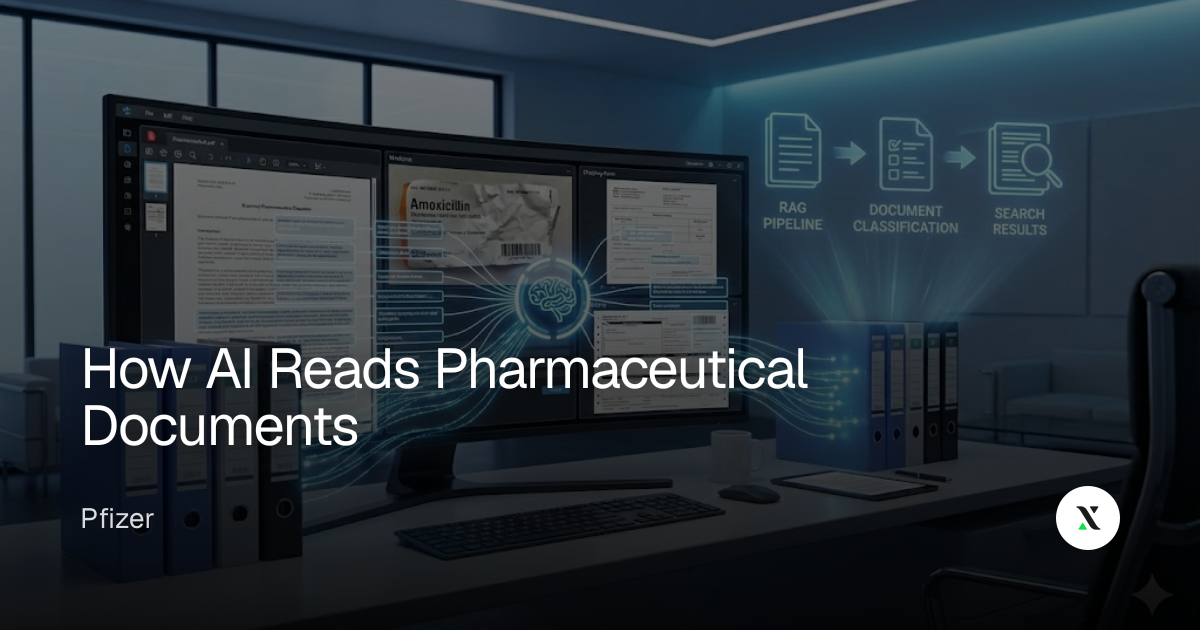
The work prototyped AI document-insight capabilities for enterprise pharmaceutical PDFs, mapping OCR, LLMs, RAG, and computer-vision components into a coherent processing pipeline. The deliverables documented an OCR→entity-extraction→classification approach, noted inconsistencies in vendor documents, and proposed using Neo4j and improved retrieval to enable pattern recognition.

Pfizer Advanced: AI-Powered Document Insights & Data Extraction Externship

What I've accomplished

I produced a concrete OCR→entity-extraction→classification pipeline design, identified inconsistent date formats and a specific mismatch between a pharmacopoeia compliance date and product manufacture dates, and recommended Neo4j plus retrieval improvements to support pattern recognition.

Project breakdown

I reviewed sample vendor documents, noted inconsistent date formats and a mismatch between a pharmacopoeia compliance date and product manufacture dates, and proposed an OCR→entity-extraction→classification pipeline with Neo4j and improved retrieval to enable pattern recognition.

View all work

decifur.ai , Biomedical RAG Research Assistant

Designed and built a hybrid RAG pipeline combining Neo4j knowledge graphs, FAISS dense retrieval, BM25 sparse search, and reciprocal rank fusion to eliminate siloed retrieval over a 300+ paper biomedical corpus, demonstrating proficiency with structured reasoning approaches and NLP-/ontology-powered layering. Achieved a 35% improvement in answer relevance over single-retriever baselines. Integrated UMLS/BioPortal entity normalization and Persistent Conversational Context (PCC) memory into the query pipeline using prompt engineering and in-context learning (ICL) to ground multi-turn scientific Q&A in domain ontologies , reducing entity disambiguation errors by ~40% across evaluation queries. Fine-tuned Qwen3.5-27B on 7,700 biomedical chunks (CPT) + 1,515 Q&A pairs (SFT) via Unsloth/TRL on RunPod H100/A100 , to adapt the base model to chemotaxis research language , achieving 87% answer accuracy on held-out domain Q&A vs. 61% for the off-the-shelf model.

Neo4jFAISSBM25UMLSBioPortalQwen3.5-27BUnslothTRLRunPodH100A100
View all work

AgentIQ , Autonomous ML Pipeline Orchestrator

coordinated a 6-stage autonomous ML pipeline (EDA → Feature Engineering → Architecture → Training → Evaluation) using LangGraph for multi-agents with a cross-agent shared memory journal , to eliminate manual handoffs between pipeline stages , reducing end-to-end experiment setup time by 70% vs. a manual baseline. Implemented a self-reviewing agent loop (generate → critique → revise) for structured output validation, backed by Firebird persistence and LangSmith for AI observability , to catch and correct suboptimal modeling decisions without human intervention , improving final model evaluation scores by an average of 22% across 10 benchmark datasets. Built a FastAPI backend for RESTful API conventions + HTML/JS frontend with MLflow for MLOps and experiment tracking , to make autonomous pipeline runs fully auditable and reproducible , enabling 1-click re-run of any prior experiment with full hyperparameter and metric history preserved.

LangGraphFirebirdLangSmithFastAPIHTMLJSMLflow
View all work

Accelerator Optimization Copilot

Developed a trace-driven simulation platform generating realistic Transformer and CNN memory access patterns across configurable DL accelerator specs , to benchmark cache policy impact under real workload conditions , producing 10,000+ synthetic traces covering 5 distinct accelerator configurations. Implemented and benchmarked LRU, LFU, and a custom LLM-driven tensor-reuse scheduler side-by-side , to quantify the advantage of predictive eviction over reactive policies , showing the LLM scheduler achieved 31% higher cache hit rates and 18% lower memory capacity consumption vs. LRU. Built an interactive visualization dashboard tracking cache hit rates, memory capacity, and compilation overhead per policy , to surface per-layer optimization opportunities for ML hardware teams , enabling targeted configuration changes that cut simulated inference latency by 24%.

View all work