Pfizer logoPfizer Externship via Extern
Mithun V Gowda portrait

Early-career AI engineer focused on document intelligence

I prototype AI systems that extract and summarize data from enterprise PDFs using OCR, LLMs, and RAG to make document workflows faster and more reliable.

Work samples

Portfolio work centers on prototypes that automate extraction, indexing, and question-answering over enterprise PDFs, combining OCR, LLMs, and RAG methods.

  • Pfizer Advanced: AI-Powered Document Insights & Data Extraction Externship
    Pfizer logo

    Pfizer · ✅ Verified by Extern · ⏱️ In progress

    Pfizer Advanced: AI-Powered Document Insights & Data Extraction Externship

    Prototype AI-powered document intelligence with Pfizer—using OCR, LLMs, and RAG to automate real enterprise PDF workflows and build a standout portfolio project.

    AI & MLPythonDocument IntelligencePresentation Skills
  • Zomato AI Data Platform
    Zomato AI Data Platform

    Delivered an end-to-end ELT pipeline handling 10M orders, 23M order items, and 300K reviews, by loading S3 data into Snowflake through a keyless IAM integration and modeling it with dbt into Bronze/Silver/Gold layers with incremental MERGE facts that process only new rows instead of full rebuilds. Automated the full workflow into one daily run across 4 dependent tasks (load → dbt build → LLM enrichment → AI mart), by orchestrating an Airflow DAG in Docker with credentials injected through environment variables. Enabled plain-English analytics through 3 AI capabilities (review enrichment, RAG chat, text-to-SQL), by using gpt-4o-mini to structure sentiment/topic from free-text reviews, embedding-based retrieval for grounded answers, and a SELECT-only guard on generated SQL, all served in Streamlit.

    PythonS3SnowflakeAirflowDockerOpenAI APIdbtStreamlitgpt-4o-mini

About me

I prototype AI systems that extract and summarize data from enterprise PDFs using OCR, LLMs, and RAG to make document workflows faster and more reliable.

Software Engineer with 3+ years building Python backend services on AWS, plus hands-on RAG and multi-agent LLM work, AI integrations, and production-oriented backend systems

Externships

Pfizer Advanced: AI-Powered Document Insights & Data Extraction Externship

In progress

Experience

AI Research Assistant

Binghamton University - SUNY · Jan 2026 – Present

AI Engineer

Extern · Sep 2026 – Present

Software Engineer

ITC Infotech Pvt Ltd · Jan 2022 – June 2024

Education

Binghamton University - SUNY, New York

Master’s in Computer Science | 3.67 / 4.00 GPA · Class of 2026

Skills

RAGGraphRAGAgentic ArchitecturesMCPOpenAI APIFAISSBM25Prompt EngineeringAWSDockerKubernetesGitHub ActionsCI/CD PipelinesPythonSQLJavaScriptTypeScriptShell ScriptingJavaFastAPIDjangoFlaskDjango ORMRESTful APIsMicroservicesPyTestPostgreSQLMongoDBMySQLRedisPower BIGrafanaReactNext.jsHTML5CSS3GitPostmanOpenAPIGitHub CopilotAI-Assisted Coding Workflows

✅ Verified by Extern · ⏱️ In progress

Pfizer Advanced: AI-Powered Document Insights & Data Extraction Externship

Prototype AI-powered document intelligence with Pfizer—using OCR, LLMs, and RAG to automate real enterprise PDF workflows and build a standout portfolio project.

AI & MLPythonDocument IntelligencePresentation Skills
Overview

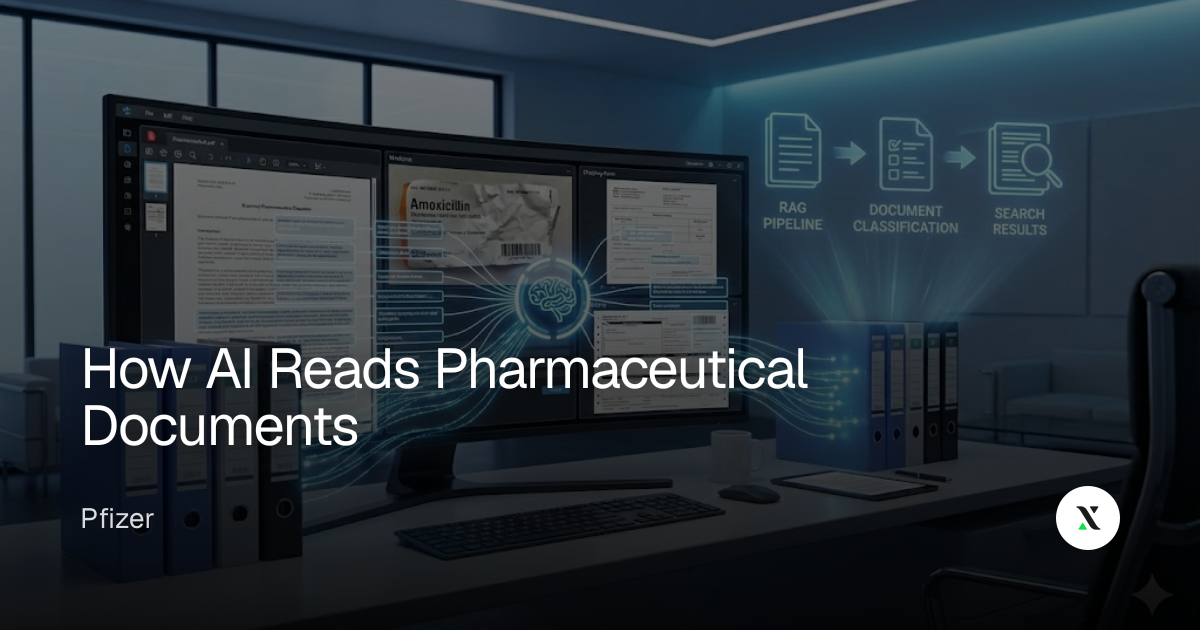
The externship produced a prototype workflow that connected OCR, retrieval-augmented generation, and language models to process enterprise PDFs. Deliverables included a survey of LLM architectures and technical notes describing component interactions. The work documented how models handle structured and unstructured pharmaceutical documents.

Pfizer Advanced: AI-Powered Document Insights & Data Extraction Externship

What I've accomplished

I documented LLM behavior and training: defining an LLM as a predictive-text model trained on billions of pages, outlining its masked/next-word training dynamics, noting human-guided fine-tuning, and clarifying it does not learn from live chats after training.

Project breakdown

I described an LLM as a predictive-text model trained on billions of pages to predict the next word, explained its practice-of-hidden-words training, and noted human-guided fine-tuning and that the model does not learn from live chats after training.

The module required preparing scanned pharmaceutical documents. I developed a multi-step Python pipeline in Google Colab that applied non-local means denoising, CLAHE contrast enhancement, and adaptive thresholding to produce a cleaned, binarized image ready for OCR.

The task processed a 3-page SDF with PyMuPDF, extracted nearly all words and their bounding boxes, and saved page-level structured JSON. The submission documented layout challenges (tables, multi-column flow) and included the extraction code and a word-count snapshot.

Google Docs
Access

I ran three OCR engines on a pharmaceutical supplier scan, analyzed detection versus recognition behavior, noted preprocessing and setup issues, and recommended using EasyOCR or PaddleOCR for layout with Tesseract as a cross-check; I produced a comparison report.

Google Docs
Access

During the externship I designed, implemented, and evaluated a RAG pipeline that ingested multi-page PDFs, applied page-level chunking, used sentence-transformer embeddings with hybrid vector+BM25 retrieval, and added a cross-encoder reranker; the deliverable included an architecture report and…

Google Docs
Access
View all work

Zomato AI Data Platform

Delivered an end-to-end ELT pipeline handling 10M orders, 23M order items, and 300K reviews, by loading S3 data into Snowflake through a keyless IAM integration and modeling it with dbt into Bronze/Silver/Gold layers with incremental MERGE facts that process only new rows instead of full rebuilds. Automated the full workflow into one daily run across 4 dependent tasks (load → dbt build → LLM enrichment → AI mart), by orchestrating an Airflow DAG in Docker with credentials injected through environment variables. Enabled plain-English analytics through 3 AI capabilities (review enrichment, RAG chat, text-to-SQL), by using gpt-4o-mini to structure sentiment/topic from free-text reviews, embedding-based retrieval for grounded answers, and a SELECT-only guard on generated SQL, all served in Streamlit.

PythonS3SnowflakeAirflowDockerOpenAI APIdbtStreamlitgpt-4o-mini
View all work

Change Request System

Developed a full-stack change-management platform with requester, approver, and admin roles, improving UI interaction efficiency by 40%, by implementing hashed-password session auth, CSRF-protected validated forms, and role-scoped dashboards, request lists, and access checks. Modeled a Draft → Submitted → Under Review → Approved/Rejected lifecycle, by designing a relational schema (users, requests, approvals, comments) with per-level approval tracking, timestamped reviewer decisions, and cascading relationships, containerized with Docker.

PythonFlaskSQLAlchemySQLiteFlask-LoginDocker
View all work